


With the AI market experiencing some volatility and a pull back, it’s an interesting time to analyze the narratives of the some of the biggest AI bears. Some of those I find fairly interesting are Michael Burry, Yann LeCun, David Cahn, Ed Zitron, Jim Covello, Steve Eisman, Melanie Mitchell, Molly White, Abi Awomosu, David Rosenberg, Stacy Rasgon, Dean Baker and Gary Marcus.
What do European Voices have to do with the American AI Bull Market?
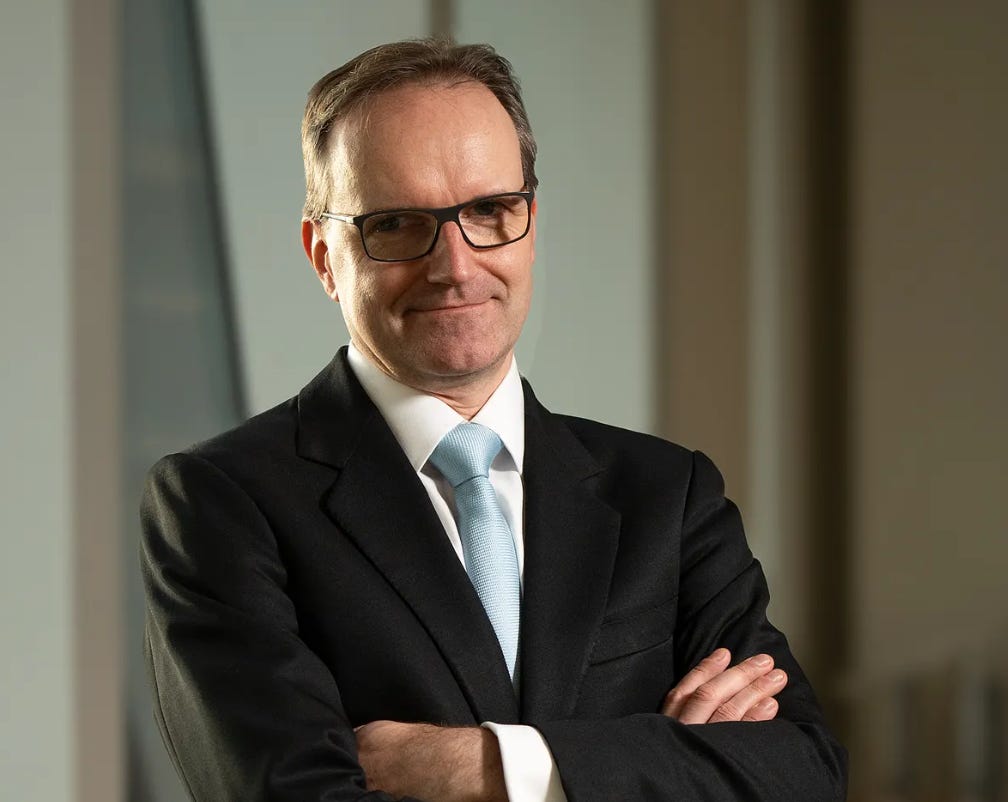
But how about in Europe? Joachim Klement is an investment strategist based in London, I asked him if I could share one of his articles for a second publication. Joachim Klement is Head of Strategy, Economics, and ESG based in London working at Panmure Liberum. Throughout his professional career, Joachim focused on economics, geopolitics, ESG and their impact on financial markets.
Now I may have a soft spot for Mathematicians who predict World Cup football winners, but when the AI optimist thesis gets shaky, that’s when I think we should be reading these diverse takes on the AI bubble for the informed context and even predictions.
Klement on Investing
A lot of economists who are involved in AI write very unrealistic reports, but I myself prefer realism.
Thesis on SLMs
Joachim Klement’s view on small language models (SLMs) and edge device inference serves as a primary catalyst for his broader macro AI bear thesis. Rather than viewing local AI as an additive trend, he sees it as a structural threat to the economic assumptions driving centralized hyperscalers.
When I first read his summary and position, I found it so persuasive I contacted him immediately. I will add that the DeepSeek moment, never really went away. And I think Claude Mythos 5.2 will do great. I just believe how the world uses these models is also going to change.
“My core conviction is that the AI bubble will either burst in 2027 or in 2028, so sometime in the next two years,” Klement said in an interview.
Selection of Klement
October 9th, 2026 segment (video) with Bloomberg, that summarizes our thesis today.
Jensen Huang affair not on my Bingo Card (CNBC).
China is decoupling from the West
Europeans really don’t like to invest in stocks
It’s not you, it’s your AI
Themes and Highlights
As the Generative AI cycle matures it won’t just be more capable models, agents and open-source counterpoint guiding consumption patterns.
🔸 The Death of the "Bigger is Better" Paradigm
🔸 Upfront Capex vs. Edge Efficiency
🔸Margin Compression and Unprofitability
🔸Hardware Pivot as a Hedge
In Klement's view, the future of AI technology will be small, efficient, and cheap—making the business model powering centralized cloud AI structurally unprofitable.
In recent interviews Klement has stated he could see the S&P 500 falling to around 5,000 by end-2027. Currently it rests at about 7,500. That’s only a 33% drop. Historically the S&P goes up 7-10% a year, but since 2020 it’s been up 16.4%. That’s not normal. Mean reversion is its own kind of realism, whatever the external catalysts (or theories or narratives) may be.
Mythos / Fable 5.2 is a Superb Model
The model is significantly better and faster. Fable 5.2 and Mythos 5.2 also comes with an optional fast mode, which speeds up token generation by up to 2.5 times. They already generate outputs 30% faster than their predecessors. The launch marks the first time that Anthropic has released a “frontier” model since AI Execs like Dario Amodei were calling for a slowdown. Anthropic will have to IPO significantly lower than previously anticipated.
“We called for pacing, not pausing,” Dianne Penn, Anthropic’s head of product management
Anthropic is clearly the frontier model builder and AI Lab of its generation. Though I wouldn’t count the likes of DeepSeek out quite yet. The most stand-out feature of Mythos 5.2 is how it redefines autonomous engineering thus allowing Anthropic’s cadence of new model releases to be noticeably faster. The model now is better equipped and admits when it doesn't know things instead of hallucinating.
It’s been almost three months since this article was first published, but in view of the almost bear market on Semis, Neo Clouds and pressure on the AI sector, I think it deserves fresh eyeballs.
Read the following very carefully. If you were an executive at Apple, you might have paid special attention to this point of view and indeed in 2023 itself. If you value his unique takes, please support the author and signal your appreciation for the analysis.
If this is true, the hyperscalers are toast
In my regular research (behind a paywall), I have been saying for a while that I think the future of AI is not large language models (LLM), but small language models (SLM) run on local desktop computers or even mobile phones. In May, a team from Stanford University published research that compared these SLMs with the performance of LLMs run in data centres. If their results are true, then we will hardly need any data centres in the future, and the hyperscalers are wasting hundreds of billions of dollars in investments.
Seriously, if you are an investor trying to figure out where to invest in the AI hype, you need to read this paper in full. But to get you started, let me give you some highlights.
First, they ran a series of SLMs (QWEN 3, GEMMA 3, GPT-OSS, GRANITE 4.0) that can be downloaded on a local PC and compared their performance with cloud-based state-of-the-art LLMs (ChatGPT 5, Claude Sonnet 4.5, Gemini 2.5 Pro).
They ran these SLMs on local PCs powered either by an Nvidia chip or an Apple M4 chip, as they are readily available in current high-end desktop computers (the entire study was done before Nvidia presented its AI chip for PCs, which will only accelerate the move away from datacentres to models run on desktops).
Then they traced the performance of these SLMs vs LLM between 2023 and October 2025 on both chat tasks and reasoning tasks.
The chart below shows the Win/Tie-ratio for SLMs vs LLMs in chat requests, which still make up the vast majority of requests today. As you can see, in every domain, the best SLM is able to find the same or better answers than an LLM in 90% or more of the cases, with an average across all domains of 98.6%.
Win/Tie-ratio of SLM vs. LLM in chat requests

When it comes to reasoning tasks, which are obviously more demanding, SLMs are catching up fast. On average, they provide a better or at least as good an answer as LLMs in 62.5% of the cases.
Win/Tie-ratio of SLM vs. LLM in reasoning tasks

However, in real life, the tasks for SLMs and LLMs are typically a mix of chat requests and reasoning tasks, so the third chart shows the weighted average of chat request performance and reasoning performance based on the frequency of tasks in each domain. As you can see, on average, SLMs are as good if not better than LLMs in 81.2% of the cases, with the LLMs having a significant advantage only in areas like engineering, life sciences, transportation and computer sciences.
Win/Tie-ratio of SLM vs. LLM in chat and reasoning tasks

But it’s not just accuracy. SLMs achieve this performance at energy and compute costs that are between 50% and 85% lower than for an LLM, depending on the SLM and hardware used in the computer.
What is more, SLMs are catching up rapidly in reasoning tasks. The final chart shows the performance of SLMs as a function of difficulty level and model generation for reasoning tasks alone.
In 2023, the success rate of SLMs in reasoning tasks was typically 50% or so across all five difficulty levels. By October 2025, the SLMs achieved 99% success for the easiest reasoning tasks in levels 1 and 2, 85% to 92% success in harder tasks (levels 3 and 4) and only lagged LLMs in the hardest tasks of level 5 (51.5% success rate).
Success rates of SLMs in reasoning tasks

This already means that one can replace data centres and their expensive cutting-edge semiconductor infrastructure in four out of five use cases. The research report estimates that the addressable market in the US for SLMs has grown to about $10tn or one-third of the entire US GDP of $30tn. There isn’t much left for LLMs to thrive in, and every year, their advantage over SLMs is shrinking.
There clearly are areas where LLMs are still way ahead, particularly in agentic AI applications, where SLMs currently only achieve accuracy and success rates of less than 50%. Similarly, it is difficult to run these SLMs on smartphones so far. The models that can be run on an iPhone are significantly worse than the models that can be run on a desktop PC.
But – and this is important – the models run on a desktop PC, and even more so, the ones run on a smartphone are much more energy efficient than the ones run in the cloud. The inference per Watt of these SLMs is typically seven times larger than that of LLMs. And that means that when you encounter a task that can be solved on a desktop or even a mobile device, it is cheaper to do so locally than send it to a data centre.
This has important implications for investors, in my view:
We need many fewer data centres than we think. If we can already replace 70% to 80% of the tasks that are expected to run on LLMs with SLMs, the hyperscalers have simply no revenue growth in the future that is nearly enough to justify the capex. In fact, if this research is true and this trend continues, data centres may be the worst investment in the AI space one can make right now.
While we continue to need enormous investments in semiconductors of all sorts, we do not need to invest in the most advanced Nvidia chips. The cheaper ones that run on desktop PCs will be enough. The best case for Nvidia is that it can replace its high-end data centre GPUs with its new chips for desktop PCs. What will that do to Nvidia’s margins and revenue growth going forward?
We still need LLMs for the most advanced tasks, and companies like OpenAI, Anthropic and others will be able to ‘dumb down’ their models to an SLM and sell them instead of LLMs. But given the already fierce competition from Chinese providers like QWEN or IBM’s GRANITE, the profit margins for these models will be much smaller than for LLMs. So what does that mean for the valuation of these companies in their planned IPOs and their growth trajectory?
While agentic AI is still better on LLMs, this may only be a temporary advantage, similar to what we have seen in reasoning tasks and single chat requests. If that is the case, the true winners of the AI boom will not be the providers of advanced hardware and data centres but the boring manufacturers of desktop computers like Dell and Apple.
Watching this race unfold is going to be fun, and I am increasingly convinced that many people will be badly burned because they invest in the wrong technology.
End of Guest Post editorial re-stack article.
AI Supremacy needs backers
Thanks for reading! If you want to support my ability to do this as my go-to work as an independent blogger, please support. I am abysmally reliant on subscription revenue right now.
